
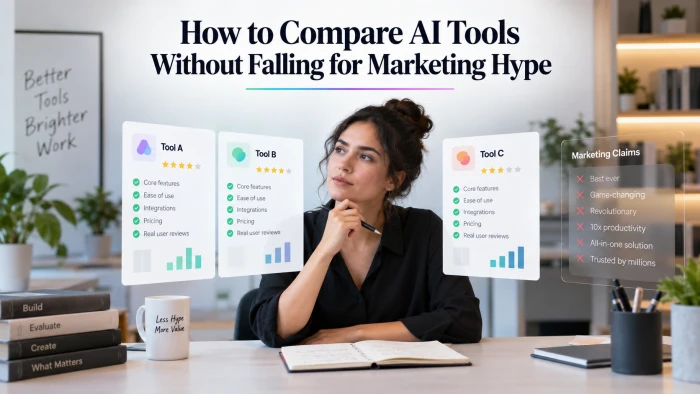
Pick almost any AI product page and you will read the same promises. It is faster, it is smarter, and it was built for teams exactly like yours. The demo runs smoothly, the numbers are large, and the testimonials glow.
None of that tells you whether the tool will work for the specific job you have in mind. Hype is rarely a lie. It is a carefully chosen best case. Your task when comparing tools is to move the test away from their best case and toward your real one.
The method below does that in seven steps. It works whether you are choosing a chat assistant, a coding helper, a transcription service, or a document analysis API. None of it requires a data science team. It requires a little patience and your own examples.
Start with your problem, not their feature list
Marketing is organized around features, because features are easy to list and easy to admire. Good decisions are organized around problems. Before you open a single pricing page, write down the exact task you need done, the input it starts from, and what a correct result looks like.
Be concrete. "Summarize support tickets" is a wish. "Turn a 400 word customer email into a 3 line summary that keeps the order number and the requested action" is a task you can actually test. The second version already tells you what to measure.
WORKFLOW How to write a testable task
step 1 Name the job in one plain sentence | → | step 2 Describe the exact input it starts from | → | step 3 Define what a correct result contains | → | step 4 Set the bar that counts as good enough |
When you lead with the problem, most of the feature list turns into noise. You end up caring only about the parts that move your task forward, and that shorter list is far easier to judge.
Turn the demo into a test you control
A demo is a performance. The vendor chose the input, the timing, and the camera angle. To learn anything real, you have to run the tool on inputs you chose, and the messier and more typical those inputs are, the more you will learn.
The useful test is the boring one you run yourself, on your own inputs, at your own desk. It rarely photographs well, which is the point.
Collect a small set of real examples, roughly 20 to 50, and be sure to include the awkward cases you already know cause trouble. Run every candidate on the same set, keep the inputs identical so the comparison stays fair, and save each output so you can look again later without rerunning anything.
WORKFLOW Running a fair head to head
step 1 Gather 20 to 50 real inputs | → | step 2 Add the hard and unusual cases | → | step 3 Run every tool on the same set | → | step 4 Save all outputs to compare later |
The first time you do this, a familiar thing happens. The tool that looked best in the demo is often not the one that handles your ugly inputs best. That single discovery usually pays for the whole exercise.
Measure what actually matters
Once you have outputs, compare them on more than a gut feeling. Five dimensions cover most decisions. Rate every candidate on all five, so a single strong number cannot hide a weak one.
Measure a handful of things that map to your task. A wall of metrics is easy to produce and hard to act on.
Public leaderboards such as the Stanford University AI Index are useful for a sense of the field, but they measure someone else's tasks. The only benchmark that settles your decision is the one built from your own work.
Here is what each dimension means in practice:
quality How often the output is correct and usable, judged on your examples | speed Typical time per request, as a median and a slow case, not the best run | cost Real price at your expected volume, including retries and long inputs | reliability Behavior under load, on odd inputs, and on the service's bad days | fit Effort to connect it to your systems, and how hard it is to leave later |
Put the results in a plain table. This is more honest than any feature grid, because every cell comes from your test rather than the vendor's claims.
Example comparison, filled in from your own test set
| Measured on your data | Tool A | Tool B | Tool C |
|---|---|---|---|
| Task success rate | 92% | 86% | 71% |
| Median latency | 1.9s | 0.8s | 3.4s |
| Slow case latency | 4.1s | 2.2s | 9.7s |
| Cost per 1k tasks | $14.00 | $6.50 | $3.20 |
| Handling of hard inputs | Strong | Mixed | Weak |
| Integration effort | 2 days | Half a day | 1 week |
Read across, not down. Tool B is fastest and cheap to connect, Tool A is the most accurate but pricey, and Tool C is cheap per task but slow and shaky on hard inputs. Which one wins depends entirely on the task you wrote down in step one.
Build a small eval you can rerun
The one time test above is good. A test you can run again is far better, because tools change almost weekly and your needs shift too. An eval is simply your example set plus a way to check the answers, saved so you can press play whenever a new version ships.
It does not need to be fancy. A spreadsheet with inputs, expected results, and a column for each tool is a real eval. This habit mirrors how formal programs like the NIST AI Risk Management Framework treat evaluation as something ongoing rather than a one time check. If outputs can be scored automatically, do that. If a person has to judge, write a short rubric so two people score the same output the same way.
WORKFLOW The evaluation loop, run it on every change
1 A new tool or a new version appears | → | 2 Run your fixed example set through it | → | 3 Score the outputs against your rubric | → | 4 Compare to the last result and decide |
| ↺ Repeat the whole loop whenever a tool or version changes | ||||||
Now every future comparison costs minutes instead of days. Better still, you will catch the moment a tool quietly gets worse, which happens more often than any release note admits.
Read the marketing like a skeptic
You still have to read the marketing. You just read it differently. Certain phrases are signals that a claim is thinner than it sounds. None of these mean a tool is bad. They mean you should ask for the detail hiding behind the words.
There is even a name for the deeper trap. Goodhart's law holds that once a number becomes the target, it stops being a good measure. A benchmark a whole industry optimizes for tells you less over time, which is exactly why your own test matters.
| Phrase worth a second look | The question to ask |
|---|---|
| "State of the art" | With no date and no named benchmark, this expires fast. Ask: state of the art against which test, and measured when? |
| "Up to 10x faster" | "Up to" describes the luckiest case, not the one you will get. Ask: what is the typical result, on an input like mine? |
| "Beats the competition" | A benchmark with no link to its method is a claim, not a result. Ask: can I see how this was measured? |
| "Flawless in the demo" | A tool that never shows a mistake is hiding its edges, not missing them. Ask: can you show me where it fails? |
| "Enterprise grade" | This usually describes a sales motion, not a capability. Ask: which specific feature does that phrase refer to? |
The cure for a vague claim is a specific question, asked about a case that looks like your own.
Count the total cost, not the sticker price
The headline price is the smallest part of what a tool costs. Procurement teams call the full figure the total cost of ownership, and it is where a cheap sticker price often loses to a pricier tool. Add the pieces that appear later, because they decide whether the cheap option stays cheap.
The number on the pricing page is a starting point. The number that belongs in your decision is everything stacked on top of it.
WORKFLOW What total cost actually adds up to
base Sticker price per request or seat | + | scale Longer inputs, retries, and busy months | + | setup Engineer time to integrate and maintain | + | people Human review and switching risk later | = | true cost The figure that belongs in the decision |
A tool that costs more per request can easily be cheaper overall if it needs less babysitting. The reverse is just as common. A low price per call means little if a person has to review every output by hand.
Score it, then decide
Put everything in one place. Give each dimension a weight based on what your task needs, score each tool from your own test, and let the weighted total guide you. The score does not decide for you, but it makes your reasoning visible and easy to defend later.
| Dimension | Weight | Tool A | Tool B |
|---|---|---|---|
| Quality on your data | 35 | 9 | 8 |
| Speed | 15 | 6 | 9 |
| Total cost | 25 | 5 | 8 |
| Reliability | 15 | 8 | 7 |
| Fit and lock-in | 10 | 7 | 9 |
| Weighted total | 100 | 7.1 | 8.0 |
Then write one sentence next to the winner explaining why it won. Six months from now, when a colleague asks why you chose it, that single sentence will be worth more than the whole demo you once watched.
The short version
If you remember nothing else, remember this. Marketing shows you a tool on its best day. Your job is to find out how it behaves on an ordinary one. Bring your own inputs, measure a few things that matter, add up the cost you will actually pay, and keep the test so you can run it again.
- Wrote the task, the input, and what a correct result looks like
- Tested on 20 to 50 of my own examples, hard cases included
- Measured quality, speed, cost, reliability, and fit
- Saved the eval so I can rerun it on the next version
- Checked every marketing claim against a case like mine
- Added up total cost, not just the sticker price
- Scored the options and wrote down why the winner won
Comments 0
Join the discussion and share your perspective.
Sign in to post a comment and reply to other readers.
No comments yet
Be the first to share your perspective on this article.